A demo and a Tuesday are different kinds of things.
One runs once, for you, with the good input. The other runs every day, for strangers, on a budget, and has to fail in a way somebody can see. I build the second kind, and then I explain it to the people who have to live with it.
 Verify ↗
Start here
Four things, if you only have a minute
Use a retrieval system I built
Type a question. Watch which passages it pulls, with real relevance scores. Then ask it something it does not know and watch it refuse to guess.
02 · the failureThe week my assistant lied and nothing alerted
Every health check was green. The answers were confident, generic and wrong. This is the reason I build guards first.
03 · the translationAI explained to people without a degree in it
Forty-four articles. Every idea ships with a machine the reader can break.
04 · where I came fromClaims and insurance before a line of Python
I know what a denied claim costs a hospital, because I used to be the person who had to go and fix it.
01 · live
A retrieval assistant that admits when it found nothing
The assistant on mstimaj.com answers questions about my writing. It never receives the whole site as context. It retrieves, and when retrieval comes back empty it says so instead of improvising. This is that retrieval layer, running in your browser, on the real corpus.
The last one is deliberate. Nothing in the corpus covers it, so it shows you what happens when retrieval comes back empty.
Ask a question, or press one of the examples.
What is real here: 735 passages chunked from 44 articles published on mstimaj.com, scored the same way the live system scores, which is full-text relevance weighted by a priority column rather than vector similarity. Retrieval runs in your browser, so no key is exposed and no query is billed. Generation is not run here. The live assistant does that behind a spend cap.
02 · the failure that set the rules
Every health check was green and the answers were wrong
An assistant I built kept returning confident, generic answers for days after its model API had failed. Nothing alerted. The uptime check passed, the endpoint returned 200, the logs were clean. I caught it by reading an answer against what should have been retrieved and noticing the passage was not in there.
Whether a process ran and whether its output was correct are two different questions. Only one of them was being asked.
- So the guard came first, not last. When retrieval returns nothing usable, the assistant has to say so. It is not allowed to fill the gap.
- And the same rule went into the document pipeline. A rule engine reads the finished file and raises an error rather than shipping something that breaks its own contract.
- And into the data layer. Any write that would shrink the record is refused. That one exists because an unguarded write truncated a file and cost weeks.
A system that fails loudly is cheaper than one that fails quietly. The quiet one bills you for months before anybody notices.
03 · selected work
Three shelves
Grouped by what they are for, rather than by when I made them.
Shelf one · AI systems in production
Retrieval, and the cost of running it
The assistant above, running on a live WordPress site. Content is chunked into a full-text index and the top passages are selected per message, weighted so core material outranks incidental pages.
- Retrieval, not context stuffing. Five passages per question out of 735. The model never sees the whole site, which is what keeps the answer traceable.
- A spend cap that closes the endpoint. Per-user rate limiting on top. A demo does not need either. A thing that runs on a Tuesday does.
- Every interaction logged, and the schema versioned so a change migrates forward instead of breaking on deploy.
- Reindexing is incremental. Saving one article rebuilds one chunk. Fixing a typo does not rebuild the knowledge base.
Shelf two · automation with a brake on it
An agent-operated document pipeline
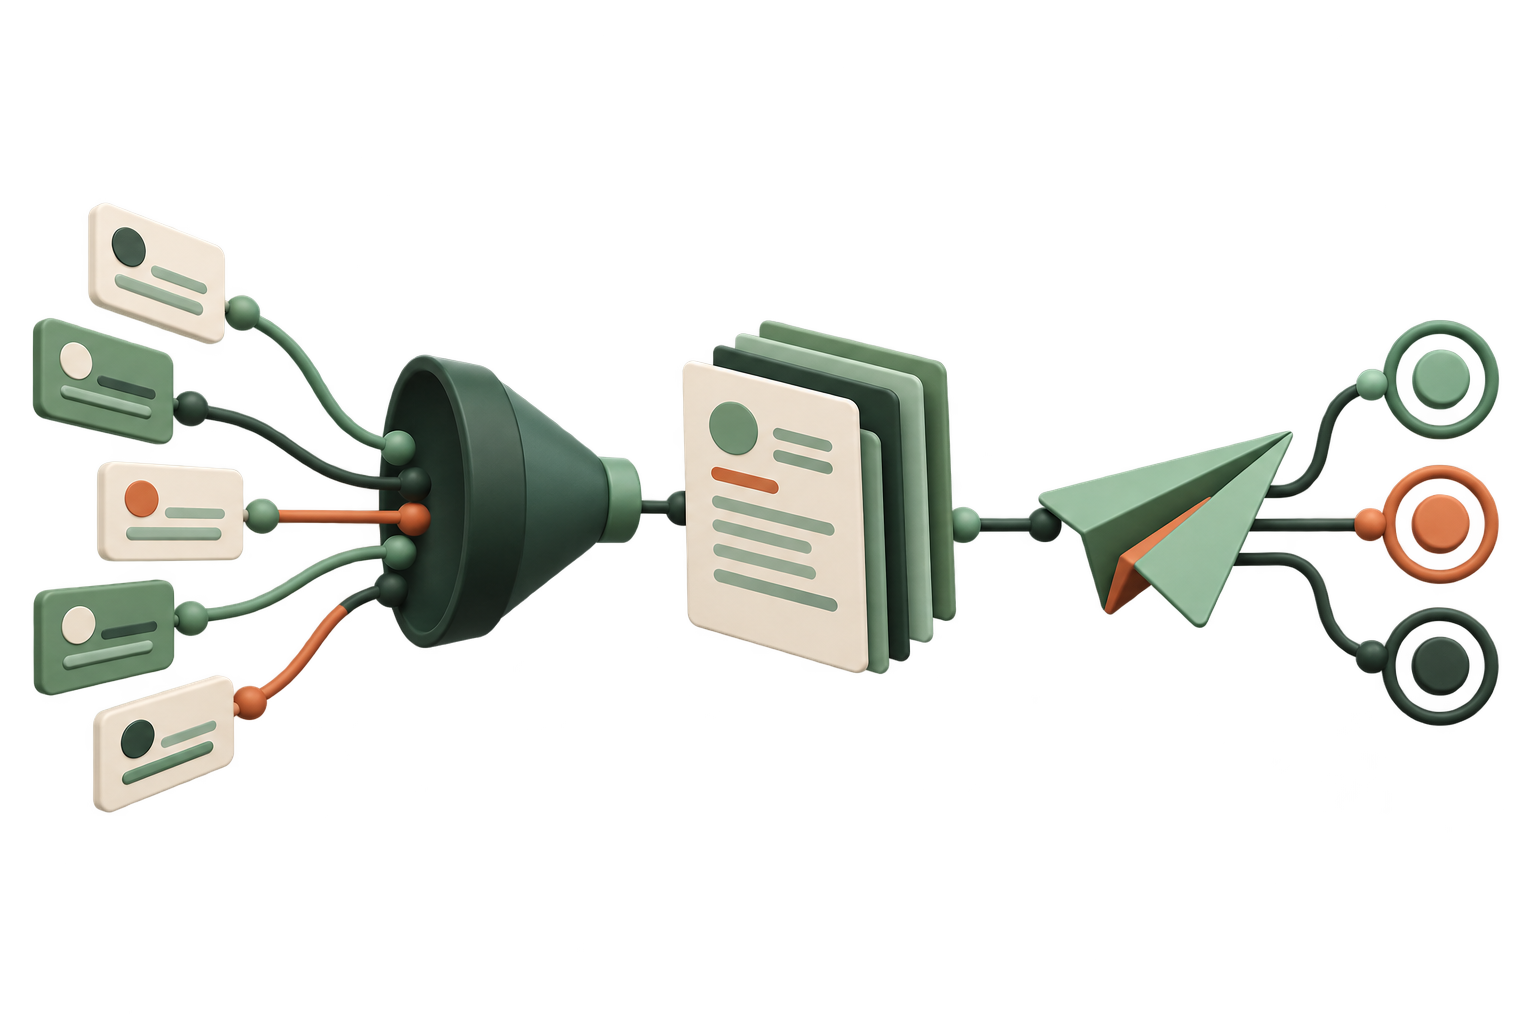
Sources live requisitions from applicant tracking system APIs, screens each against hard eligibility rules before any work happens, and generates a tailored document set for the ones that survive.
- It reads the source, not the aggregator. In one sweep, 168 listings passed a text screen. Six were genuinely what the card claimed. The rest misreported pay or location. Reading the employer's own API is now a rule rather than a preference.
- Screening runs before generation, so the expensive step never runs on something already disqualified.
- The output is inspected, not trusted. The rule engine has refused to ship more documents than I would like to admit.
Shelf three · the translation layer
Explaining AI to people who were never invited into the conversation
Forty-four articles on mstimaj.com, each shipping with an interactive machine the reader can break: change the input, watch the output move, keep the intuition afterwards.
- A tokeniser you can type into, which splits your sentence into chips and tells you plainly that it is a simplified split and not real BPE.
- A cost calculator that takes a token count and extrapolates the monthly bill, because the number people actually need is the one on the invoice.
- A retrieval toggle. Same model, same question, retrieval off and then on. Off, it hedges and nothing marks it as a guess. On, it cites.
Shelf four · one post, several platforms
Cross-posting without doing the work five times
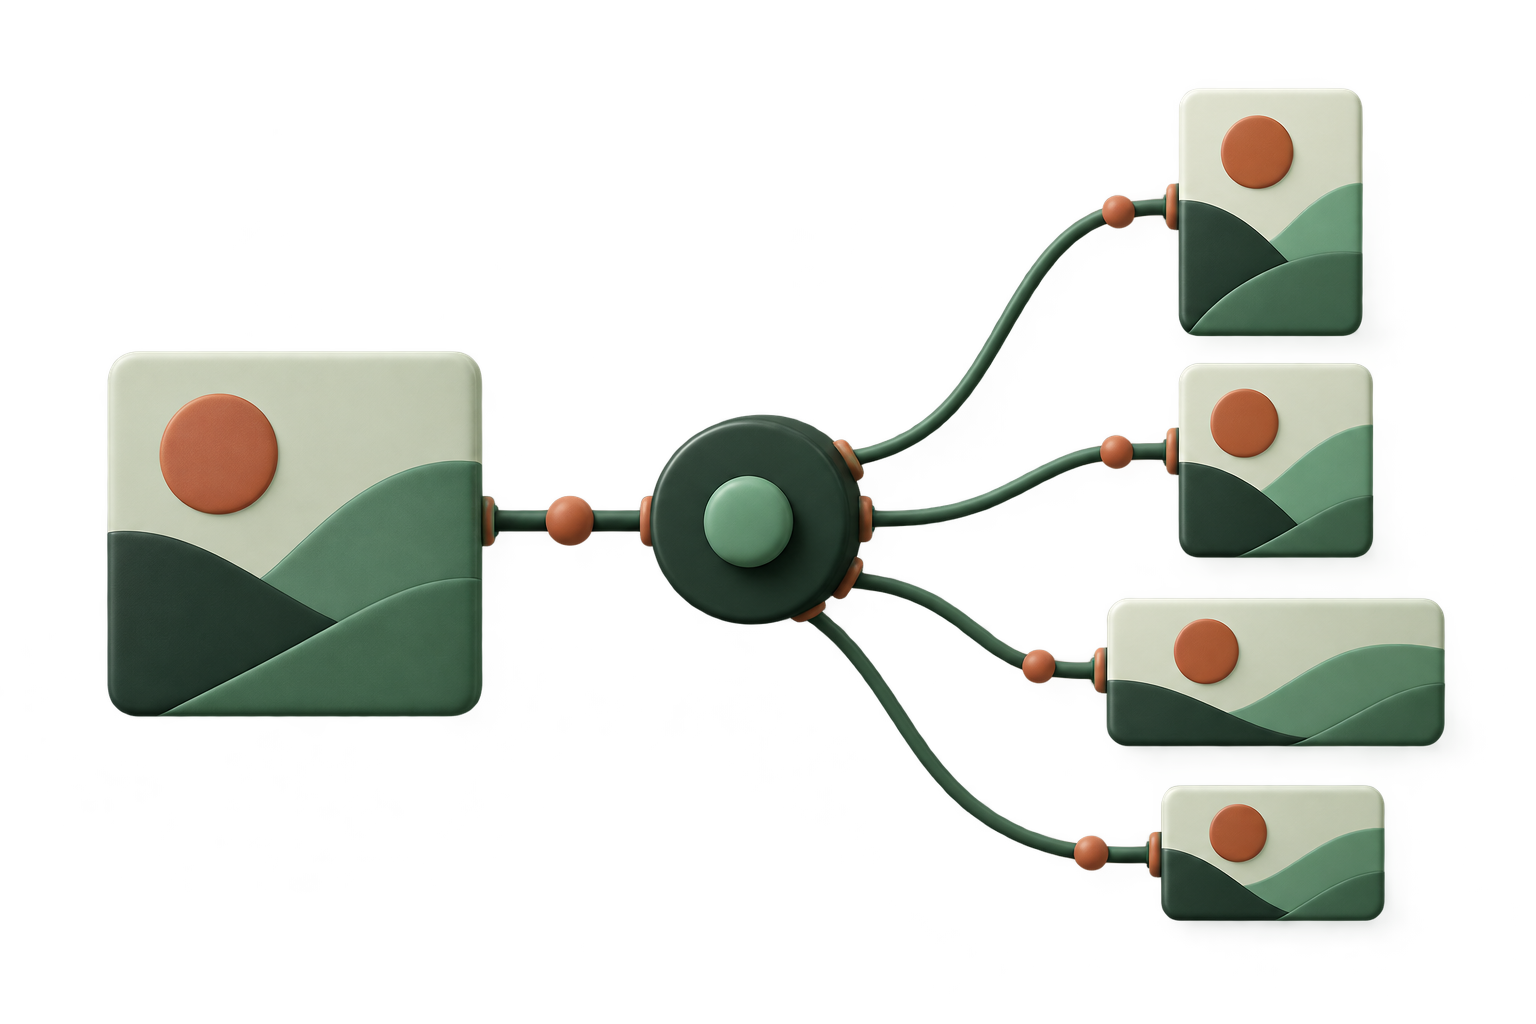
Publer wired into the Meta, X, and YouTube APIs, so one piece of content is adapted and scheduled across platforms from a single source instead of retyped per app.
- One source, several shapes. The same content gets reformatted per platform's real constraints, not just resized.
- Scheduling is the point. Posting on time matters more than posting from memory, so the queue runs on its own.
04 · where this came from
Claims and insurance before a line of Python
At Quick Med Claims I supervised the billing team on 911 and emergency medical services revenue cycle: Medicare, Medicaid and commercial payer claims, denials and appeals, end to end. Our review was inconsistent enough to expose us under payer audit, so I rebuilt the workflow, wrote the procedures, trained the team on them, and added the check that made our submissions defensible.
Before that, commercial property and casualty service delivery at Arthur J. Gallagher, coordinating underwriting, claims and operations. I know what a denied claim costs a hospital and what a bad renewal conversation costs a broker, because I was the person holding both.
Plenty of people can build a retrieval system. Not many of them have sat on the other side of the software at eight in the morning, working out why something that should have paid did not pay.
I started a company because I wanted to build things and did not want to wait for permission to do it. I write about artificial intelligence every week because the people most affected by it are the least likely to be invited to learn it, and that gap is not going to close on its own.
I am not interested in AI as a novelty. I think it is the thing the next twenty years get built on top of. I would rather be one of the people building it than one of the people it happens to.
05 · the questions recruiters ask first
Quick answers, so you do not have to email to find out
Work authorization, start date, location, and whether the AI work is real. Every answer here is one I will defend live.
Are you authorized to work in the United States?
Yes. I am authorized to work for any employer in the United States and I do not need sponsorship, now or in the future.
Do you work remotely, and where are you based?
I am in Naugatuck, Connecticut, and I work remotely for employers anywhere in the United States. I am on Eastern time.
When can you start?
Two weeks from an offer.
Have you managed people?
Yes. At Quick Med Claims I supervised the billing team on emergency medical services revenue cycle, rebuilt the review workflow, wrote the procedures and trained the team on them.
What is your degree?
Bachelor of Science in Information Technology, Sacred Heart University, May 2026. I also hold the Google AI Professional Certificate, which you can verify from the link at the top of this page.
Is your AI experience hands-on or just coursework?
Hands-on and in production. The retrieval assistant on mstimaj.com runs on a live WordPress site behind a spend cap, and the retrieval layer is on this page for you to try. I also built an agent-operated document pipeline that reads applicant tracking system APIs, screens against hard rules, and generates tailored documents, and I run Model Context Protocol servers in my daily tooling.
What is retrieval augmented generation, in plain words?
The model is not asked to remember. It is handed the few passages that actually match the question and told to answer from those only. When nothing matches, it says so instead of guessing. That last rule is the part most people skip, and it is the one I build first.
Which industries do you know from the inside?
Healthcare claims operations: Medicare, Medicaid and commercial payer claims, denials and appeals. Commercial property and casualty insurance service delivery, coordinating underwriting, claims and operations across a book of accounts at Arthur J. Gallagher.
What roles are you looking for?
Full-time, remote, United States. AI enablement, implementation, technical program operations, support engineering, and technical customer success. The common thread is building a system and then explaining it to the people who have to live with it.
What is your technical stack?
PHP and WordPress, Python, JavaScript, SQL and MySQL full-text search, Supabase, REST APIs, browser automation, and the Claude and Gemini APIs with rate limits and spend caps in front of them.
Can I see a resume?
Yes. The resume page has it on screen and as a PDF download, and the Book an interview button puts a time on my calendar.
06 · now
What I am doing this week
Looking for a full-time remote role in AI enablement, adoption, implementation or solutions engineering. Building AI-assisted systems for small business clients through Mstimaj Tech and AI. Publishing weekly on mstimaj.com. Reading everything I can find on evaluation, because getting a model to answer is the easy half.
07 · next
Where to find me
Remote, United States. I am glad to walk through any of it live, including the parts that failed before they worked.